

The multimodal promise vs. the reality of the inference invoice
Every time a next-generation frontier model arrives, engineering and product teams ask the same central question: can we finally retire our fragmented vision stack?
The pitch is undeniably appealing. On paper, replacing a sprawling pipeline of optical character recognition (OCR) engines, fine-tuned layout analysis instances, and custom detection models with a single multimodal application programming interface (API) call simplifies everything. Architecture diagrams clean up immediately, maintenance overhead drops, and engineering roadmaps look lighter.
Then the first high-volume billing cycle arrives.
Frontier reasoning engines showcase remarkable multimodal capabilities right out of the box. They interpret unstructured visual layouts, read subtle context, and solve edge-case ambiguities that historically broke standard parsers. But running production-scale workloads through flagship multimodal endpoints carries a financial penalty. Once you move from experimentation to processing hundreds of thousands of daily document pages, logistics tickets, or video frames, universal vision tokens quickly eat into gross margins.
Where universal vision tokens erode SaaS unit margins
In enterprise operations, visual data ingestion rarely scales linearly in terms of cost unless architecture is strictly managed. Defaulting to generalist frontier models introduces three primary operational friction points:
1. The tokenization penalty of visual inputs
High-resolution imagery cannot be treated like compact text prompts. Frontier models divide images into patches and map them across large token grids. A single multi-page invoice or dense technical schematic can easily consume thousands of input tokens before the model generates a single byte of structured output. In high-throughput workflows, this token overhead creates a steep cost floor.
2. Latency overhead and SLA degradation
Flagship multimodal models prioritize expansive reasoning over raw speed. When end-users expect near-instant feedback—such as real-time receipt verification, field document upload, or line-rate quality inspection—waiting several seconds for an open-ended multimodal response can degrade product utility. Specialized vision backbones, by comparison, regularly return deterministic extractions in under 100 milliseconds.
3. Overpaying for baseline extraction
According to industry observations, the vast majority of real-world enterprise visual tasks do not require broad world knowledge or complex reasoning. Instead, they require disciplined, structured extraction: pulling line items from standardized tables, reading serial numbers, or identifying missing signatures. Paying premium token pricing to extract predictable key-value pairs is fundamentally inefficient for routine operations.
The operational alternative: task-specific models and smart routing
The goal is not to abandon frontier multimodal models entirely. Rather, sustainable production architecture treats them as an escalation layer rather than the default processing engine.
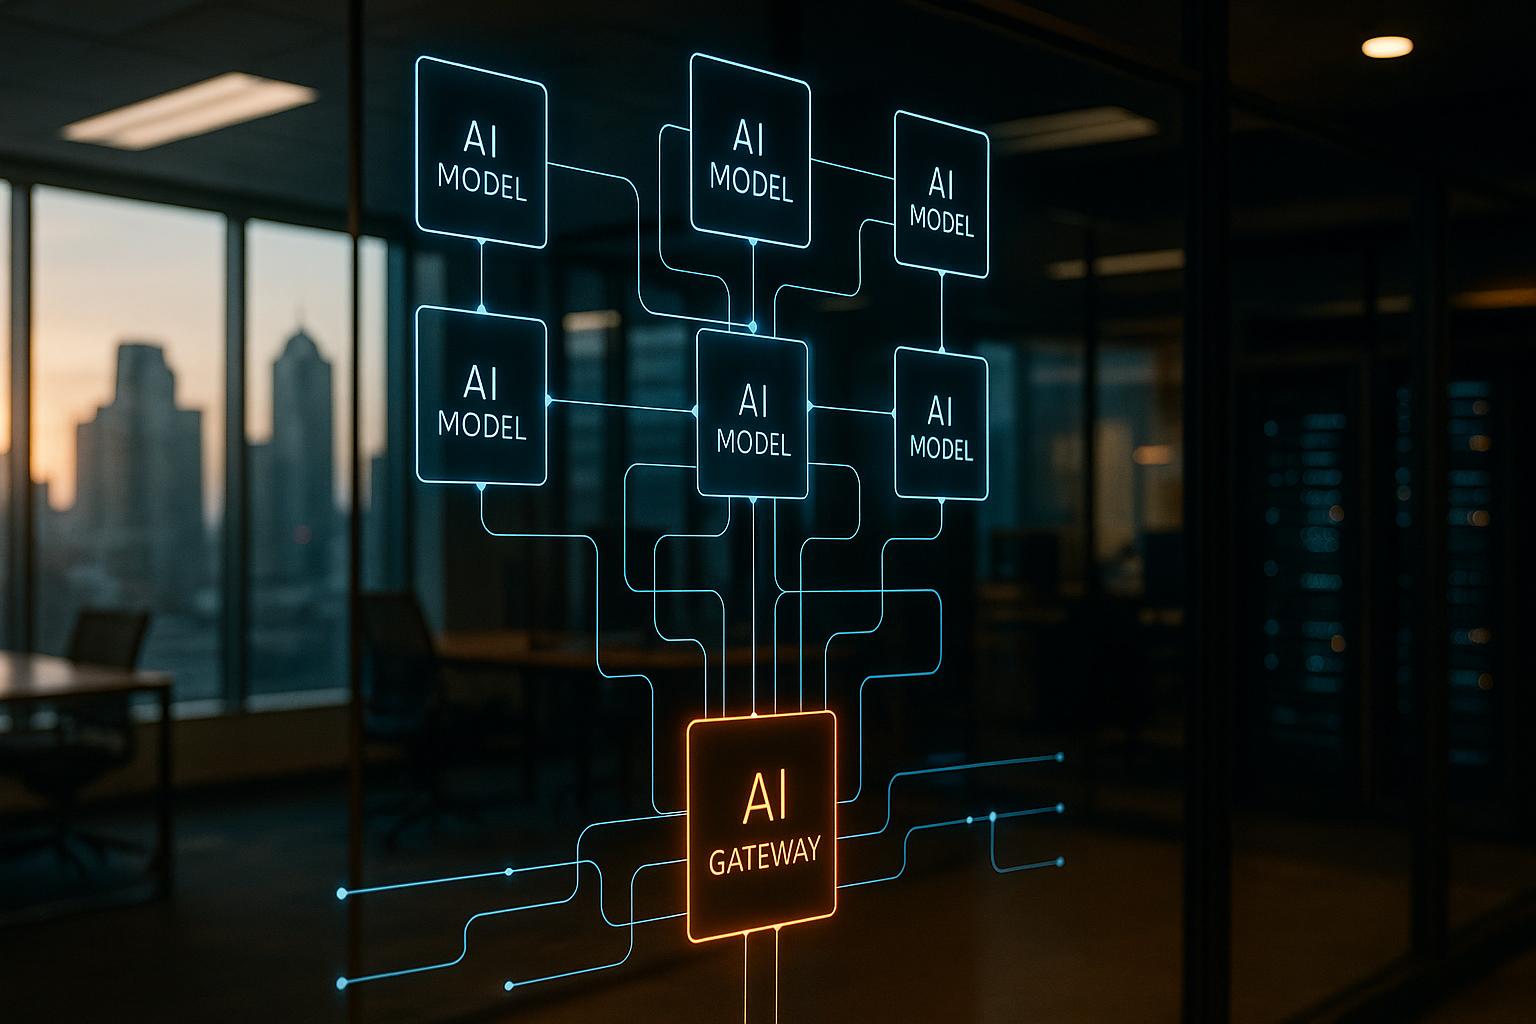
Instead of routing every visual payload through a single expensive endpoint, mature artificial intelligence architectures leverage intelligent routing:
- Tier 1 (Deterministic & Specialized): Compact, task-specific models—such as lightweight open-source vision encoders or purpose-trained extractors—handle high-volume, standardized inputs. These models run on predictable, fixed infrastructure, delivering sub-second latency at a fraction of the per-call cost of a flagship API.
- Tier 2 (Confidence-Based Routing): A lightweight validation check monitors extraction output. If confidence scores fall below a predetermined threshold or document layout deviates significantly from historical patterns, the payload routes dynamically to Tier 3.
- Tier 3 (Frontier Reasoning): Advanced models process only the complex minority of ambiguous edge cases. Here, paying premium token pricing is justified because the model resolves exceptions that would otherwise stall automation or require manual human intervention.
This tiered approach preserves product unit economics while maintaining high overall extraction accuracy across diverse datasets.
Validating architecture before deployment through systematic auditing
Adopting modern AI should strengthen operational margins, not dilute them. Rushing to consolidate an entire operational pipeline onto the latest frontier API often trades technical debt for permanent gross margin degradation.
Before committing production infrastructure to a new multimodal release, engineering leaders should audit actual workload requirements:
- Quantify workload distribution: Measure the ratio of standard inputs versus genuine edge cases across current pipelines.
- Model cost at scale: Calculate fully loaded inference costs per transaction at ten times current volume to catch hidden scaling penalties.
- Benchmark latency: Compare extraction speeds against user experience requirements and internal Service Level Agreement (SLA) baselines.
At iForAI, we work alongside engineering and operational leaders to design, stress-test, and deploy production AI architectures that balance capability with sustainable unit economics. Through our Model Evaluation and LLM Cost-Optimization Audits, we identify where workloads leak budget, engineer intelligent routing pipelines, and transfer operational capabilities directly to your internal team so you stay in full control of your infrastructure.

Inna Dzhulai
Social Media Manager at iForAI